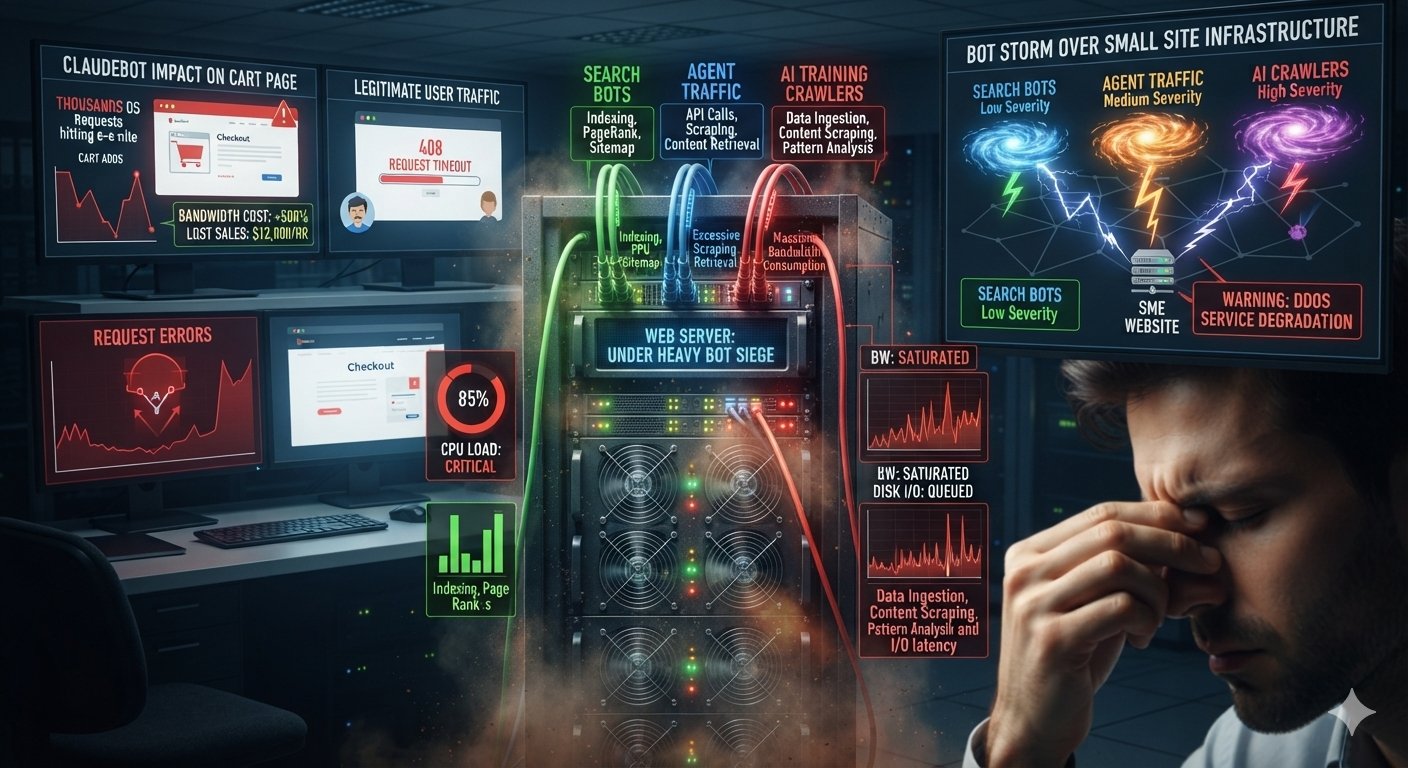
A crawler identifying itself as ClaudeBot sent 3.75 million requests to add-to-cart URLs on Kinsta-hosted WordPress sites in a single 24-hour stretch — traffic that never bought anything but still made servers work.
What this means for you
- Cloudflare put AI training crawlers at 52% of crawler requests in June 2026, up from 22% in spring 2025.
- Crawl-to-referral ratios vary wildly — hundreds to hundreds of thousands of pages per referral.
- Blocking every AI bot can also cut off search crawlers still feeding real organic traffic.
- Cart, search, and filtered pages cost far more server resources than static content ever does.
- Managed hosting can separate crawler types automatically instead of using one blanket switch.
Bot traffic isn’t one problem, it’s three
A website now has three separate crawler audiences instead of one, and they don’t behave anywhere close to the same.
Cloudflare groups automated traffic into search crawlers, agent traffic, and training crawlers. Search crawlers index pages for future results, agent traffic responds to a live user request, and training crawlers harvest content to build the next model.
That nuance is what managed hosting is built to handle.
By June 2026, training crawlers accounted for 52% of crawler requests — up from 22% in spring 2025 — and mixed-use bots for more than 36%, per Cloudflare’s July 2026 bot report. Those shares move month to month, so treat any single figure as directional.
Search-only crawling is a much smaller slice of that mix, though it still matters most for discoverability.
Agent traffic sits in between the other two. It fires when someone asks an AI tool to check availability, compare options, or pull a live answer, which means blocking it outright can remove a channel real customers are actively using.
The payoff varies wildly by crawler
Letting a bot crawl your site isn’t automatically a fair trade. Some crawlers send almost nothing back.
In Cloudflare’s 2025 Radar year-in-review data, Anthropic’s crawl-to-refer ratio reached as high as 500,000:1 and OpenAI’s peaked around 3,700:1, with Perplexity the lowest of the major AI platforms. A third-party analysis of Cloudflare Radar put Anthropic at 1,917:1 by July 2026 and OpenAI (251:1) below Perplexity (289:1) — figures we could not independently verify.
Read them as evidence of a gap, not a permanent scoreboard. They also miss value that never shows up as a click.
For a small business site, that gap isn’t abstract. A single high-volume training crawler can consume the same resources as dozens of real visitors without producing a single lead.
That’s not a reason to block every AI crawler by default. It’s a reason to ask what a specific one gives back before deciding how much access it gets.
Where the real server cost hides
The type of page a bot requests matters as much as which bot it is. A cached article costs almost nothing to serve twice.
Static pages are typically served from a cache, so repeat requests cost very little. Dynamic pages usually aren’t cached the same way, which is why the same request volume can produce very different server strain.
Cart pages, filtered product listings, internal search results, and API endpoints fall into that second group. Each one can force a fresh server response instead of a stored copy, and that’s where load actually accumulates.
That pattern showed up in Kinsta’s own analysis of bot activity across client sites. In a single 24-hour period, automated traffic generated 7.67 million requests to add-to-cart URLs, and a ClaudeBot-identified crawler accounted for 3.75 million of them.
“Automated traffic generated 7.67 million requests to add-to-cart URLs in a single 24-hour period” — Kinsta, analyzing over 10 billion requests across its infrastructure.
The problem wasn’t that an AI crawler visited these sites. It was that millions of requests hit dynamic URLs where each visit could trigger real computation.
Match the response to the crawler type
Here’s a simple gut-check for how to treat each crawler category by default.
| Crawler type | What it does | Reasonable default |
|---|---|---|
| Search crawlers | Indexes pages for search and AI-assisted search | Allow by default |
| AI search and retrieval | Answers questions using current content | Allow, monitor referral value |
| Training crawlers | Collects content for model training | Restrict if load is high, value is low |
| Unknown or excessive-rate bots | Any bot exceeding normal request volume | Challenge or rate-limit regardless of verification |
Small sites feel this faster than large ones
A large retailer with a big server budget can often absorb a spike in bot traffic without much visible effect. A small business site usually can’t.
Shared hosting plans and lean server resources mean the same volume of crawler requests takes up proportionally more of a small site’s available capacity. That’s true whether the crawler is well-behaved or not.
Waiting for a visible slowdown also costs a small operator more, because by then the traffic has been building for a while.
Building a policy instead of a switch
A blanket allow-or-block rule wastes the nuance you just learned. The better approach separates traffic by type and adjusts as behavior changes.
Search crawlers stay, training crawlers get scrutiny
Traditional search crawlers like Googlebot and Bingbot still deserve default access, since the same indexes increasingly feed AI-powered search experiences. Some hosting tools separate AI-specific bots from these crawlers entirely, so restricting one doesn’t mean losing the other.
Training crawlers get a different look. If one is crawling heavily while sending almost nothing back in referrals or citations, restricting it becomes an easier call to justify.
Access controls, not one toggle
Hosting platforms built around this problem tend to offer graduated controls rather than a single switch. Kinsta’s Bot Protection, launched June 2026, offers multiple protection levels plus a separate AI-crawler toggle that is itself all-or-nothing, with verified search bots always allowed regardless of level.
Exceptions matter just as much as blocks. A managed allow list covering common WordPress and WooCommerce paths, plus custom exceptions by IP, path, or user agent, keeps scheduled tasks and payment integrations running while stricter rules apply everywhere else.
Cloudflare moved the same way in July 2026, splitting crawler controls into search, agent, and training categories. Since September 15, 2026, new domains — plus new sites from existing customers and unchanged free-plan zones — allow search crawlers by default while agent and training crawlers are blocked on pages that carry ads.
Kinsta’s own guidance frames this as an agency-level decision, not just a site-level one: a publisher chasing AI visibility may tolerate more crawler activity than a store competing with bots for the same server resources during a sale.
Measure whether the balance is working
Bot policy isn’t a one-time setup. Traffic mixes shift, so the rules that worked last quarter might need adjusting next quarter.
- AI crawler request volume before and after a change
- Which paths get hit hardest, especially dynamic ones
- Site performance during crawler traffic spikes
- Organic search and AI referral traffic over the same window
- Conversions from any AI-referred visits you can track
If server load drops while search and AI referral traffic hold steady, the change is working. If useful traffic falls with it, the setting needs a narrower exception, not a full reversal.
A Kinsta-published case study credits the agency Hall with scaling a WooCommerce client from $3 million to more than $50 million in annual revenue after moving from WP Engine to Kinsta; recurring downtime during traffic spikes was the trigger.
It’s vendor-published, describes growth across roughly a decade of hosting, predates these bot tools, and revenue growth has many causes.
What this means for a small local business site
Most small business owners don’t have a development team to build these rules from scratch.
That’s what managed hosting is for: someone watching crawler patterns and dynamic-page load so a slow checkout doesn’t quietly cost a customer. A Pro or VIP hosting plan exists to catch that before it shows up as a lost lead.
A restaurant’s online ordering page, a clinic’s booking form, or a contractor’s quote request tool are all dynamic pages. They’re also exactly the pages a runaway crawler can slow down without anyone noticing until traffic drops.
The same logic that protects a large ecommerce brand from bot overload works for a five-page service site. The difference is who’s watching for it.
None of this requires blocking AI outright. It requires knowing which requests are worth the resources they consume.
Stop guessing which bots are costing you money. ProXSites hosting plans separate visibility-driving crawlers from the ones just burning server resources.
Sources
- Can I still benefit from AI search without letting bots destroy my server? — Kinsta (2026)
- Cloudflare, “Content Independence Day, one year on” (July 2026)
- Kinsta Bot Protection launch (June 2026)
ProXSites sells website production and hosting, including the plans mentioned above; we have no affiliation with Kinsta or Cloudflare, whose research this post cites. Kinsta’s infrastructure data and case study are vendor-published material from a company selling the bot-protection tools described.